Defensible AI: How Data Traceability Helps AI Pass the Audit
At ALIGN New York City 2026, NetApp's Jeffrey Thompson explained why auditors and litigators will ask what data a model saw, how data copies slow evidence requests, and how versioning and point-in-time replay can make AI decisions defensible.
By The AI Enterprise Magazine Team3 min read
Key takeaways
- Auditors will ask what the model saw. Thompson said teams must be able to reproduce how a model reached an answer.
- Data copies multiply risk. He cited seven to 13 copies of data across a typical AI pipeline.
- Evidence requests take too long. One customer needed six to 10 weeks to answer a request for information.
- Replay makes AI defensible. Versioning and vaulting data lets teams replay decisions at a point in time.
- Unstructured data raises the stakes. Compliance archives are becoming business context that must be governed.
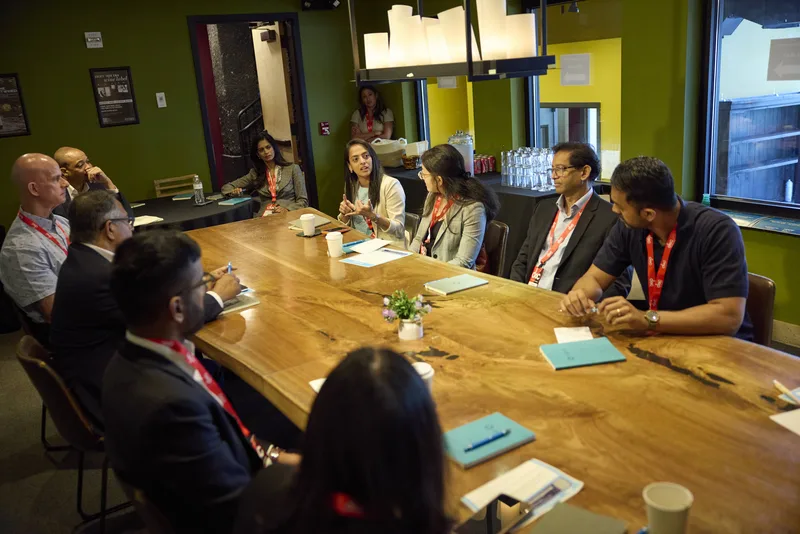
Moving AI into production means being ready to answer an auditor's question: what data did the model see, and can you reproduce its answer? Jeffrey Thompson, AI Solutions Specialist at NetApp, made that case at the ALIGN AI Executive Summit New York City 2026 on June 25, in a session sponsored by NetApp titled From Fragile Compliance to Defensible AI: Reducing Regulatory Risk Through Data Integrity. He gave a version of the talk at the Atlanta summit in May.
Why is moving AI to production a compliance problem?
Thompson, who covers financial services, said organizations are moving from small, structured data sets to larger, more dynamic and unpredictable systems while the model landscape keeps changing. Businesses want more AI use cases delivered faster, but regulators are sending mixed signals, and auditors and litigators won't give teams much leeway. "How do you move as fast as the business is demanding?" he asked, while staying safe, secure, repeatable and verifiable.
When he asks data architects how a newly launched AI capability meets specific controls, he said, the answer is almost always the same: "Don't ask."
What slows down AI audits?
Thompson described an anonymized financial services customer whose pilots stalled on the way to production. One challenge was data sprawl. He said there are typically seven to 13 copies of data across an AI pipeline, each of which has to be secured and kept current. The customer's data set was about 200 terabytes, and responding to a request for information with defensible evidence took six to 10 weeks.
Each new use case also added controls, he said, so the cost of securing data grew faster than the number of applications.
How do you make AI decisions traceable?
NetApp's approach, as Thompson described it, is a trust layer at the storage level. Metadata lets teams find data where it lives, differential updates keep large data sets current, data guardrails limit what each user sees, and a curation step converts content into formats agents can use.
The key capability is reproducibility. Versioning and vaulting data, and integrating with developer tools such as PyTorch, lets a team show an examiner how a model reached an answer, what information it was given and when, and replay that moment. The same layer supports A/B testing and checks for drift. For the customer he described, Thompson said triage time shrank from months to days, and each new use case cost less than the one before it to bring to production.
Why does unstructured data raise the stakes?
The easiest AI use cases run on clean, structured data that teams can manage by hand, Thompson said. The bigger opportunity lies in unstructured information that people create every day, but those data sets are larger, harder to predict and harder to analyze.
Data once kept only for compliance, often stored cheaply in object storage, is becoming a source of business context. That raises old questions in a new form. Teams used to worry about an unsecured S3 bucket, he said; now anyone can ask a system in natural language to reveal its secrets, so how copies are stored and exposed matters more.
He also pointed to ransomware recovery as part of the same picture, describing NetApp's snapshots and its written guarantee to restore data to a previous point in time.
What should data leaders do next?
Thompson urged AI teams to work more closely with infrastructure teams, which application teams often see as a bottleneck, and to apply one governance layer across on-premises and cloud data. He noted that NetApp runs as a first-party service on all three major hyperscalers.
His test for readiness was blunt: read another company's discovery order and ask whether you could answer it. "Can you stand up to that auditor?" he said.
Where to hear more in 2027
AI governance and data integrity will be recurring topics at the 2027 ALIGN AI Executive Summits, invitation-only gatherings for data and AI executives in eight U.S. cities. Registration is coming soon. Details are on the ALIGN AI Executive Summits page.
Frequently asked questions
What is defensible AI?
AI whose outputs can be explained and reproduced for auditors or courts, showing what data the model used and when.
Why do AI audits take so long?
Thompson pointed to data sprawl, with seven to 13 copies across a pipeline, and manual evidence gathering that took one customer six to 10 weeks.
How can enterprises make AI decisions traceable?
By versioning and vaulting data, integrating with developer tools, and keeping point-in-time records that let teams replay a model's inputs and outputs.
This article is based on remarks by Jeffrey Thompson, AI Solutions Specialist, NetApp at ALIGN AI Executive Summit New York City 2026 on June 25, 2026. More coverage: ALIGN AI Executive Summits.
Filed under: AI Governance & Trust, Data & AI Infrastructure, Security & Fraud